B2B Data Deduplication: Match Records, Not Just Names
A practical B2B data deduplication guide to matching company records, protecting CRM history and avoiding costly false merges.
4 min read · Updated 2026-10-10
Why deleting duplicate rows is not enough
Two sales reps can be working the same business without either record looking identical. One account uses a trading name; another uses the legal company name. A third arrived through an event import with a different office address. Removing rows that are exactly equal will not resolve that situation. The task is to establish which records describe the same real organisation.
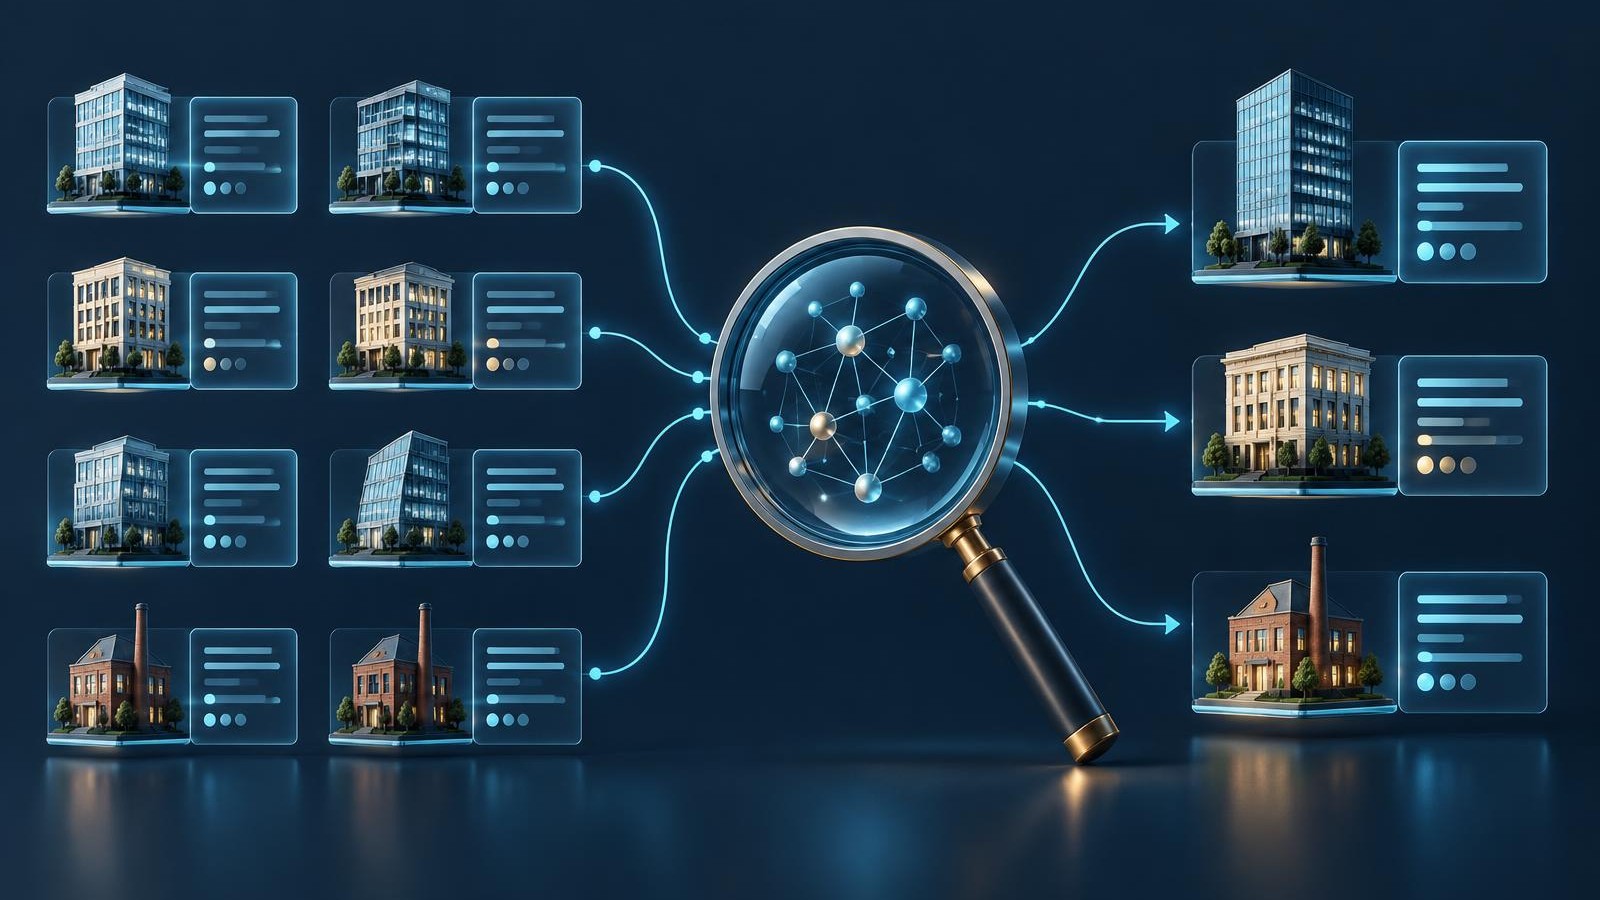
B2B data deduplication brings repeated records together. Entity resolution goes a step further: it decides which organisation or person a record represents across sources. That distinction matters when a sales database contains subsidiaries, regional branches and contacts who have changed employers. A shorter spreadsheet is not automatically a more accurate one.
Define what counts as one account before matching
Agree on the account boundary with the people who own sales territories and reporting. Are you targeting a legal entity, a corporate group, an individual branch or a buying location? Two offices belonging to the same group may need separate records if different teams buy independently. The parent relationship should connect them, not erase their differences.
Write the boundary into the research brief. For example, a campaign aimed at procurement teams may keep each operating company as an account while recording the ultimate parent separately. Without that rule, a researcher can make a technically plausible merge that breaks assignment and makes the market look smaller than it is.
Prepare matching fields without destroying the originals
Create standardised comparison fields for company names, domains, telephone numbers and addresses. Trim whitespace, make letter case consistent and separate a website hostname from tracking parameters or page paths. Keep the original value alongside the comparison value so a reviewer can see what the source actually supplied.
Treat legal suffixes and abbreviations carefully. Removing Ltd or Limited can help surface candidates, but similar names are not proof of identity. A shared registered office or switchboard can also belong to several businesses. Normalisation helps you find records worth comparing; it should not make the final decision on its own.
Use strong identifiers first and combinations second
A verified registration identifier, interpreted with its jurisdiction, can provide stronger evidence than a name alone. A domain is useful but may represent a whole group rather than one subsidiary. Compare identifiers with current company evidence, and do not assume every field labelled company ID is globally unique.
When a reliable identifier is missing, combine signals: name similarity, website, location, business activity and ownership. Separate clear matches, clear non-matches and uncertain candidates. Fuzzy matching is useful for spelling variations, but a high similarity score still needs a policy that explains what evidence permits a merge.
Keep company identity separate from contact identity
A company match does not establish that two people are the same contact. Names can repeat, shared mailboxes can serve a team and a person can move between employers. Preserve the person-to-company relationship with a date or status instead of replacing an old employer with a new one and losing the context of earlier conversations.
For contacts, compare several relevant signals, such as full name, role, employer and confirmed business contact details. Route unclear cases to review. A mistaken contact merge can attach outreach history or an objection to the wrong person, which is a more serious problem than leaving a candidate pair unresolved.
Decide which field survives before you merge
Survivorship means choosing the value retained in the final record. Make that decision field by field. Current official company evidence may be appropriate for a registered name; a recently confirmed sales conversation may be better evidence for a buying role. The newest import should not automatically replace every older value.
Preserve CRM record IDs, activity history, ownership, source records and suppression information. If one record contains a do-not-contact status, merging must not make that restriction disappear. Save a merge log showing the original IDs, chosen values and reason for the decision so the result remains explainable.
Test false merges as well as missed duplicates
Review a pilot that includes easy duplicates, similar-but-different companies and incomplete records. Checking only the obvious pairs makes the process look better than it is. Ask reviewers to identify false merges and duplicates left behind; both matter, but the cost of a false merge may be much greater for an account with active opportunities.
For example, two fictional records named Northbridge Analytics and Northbridge Analytics Services may look close enough to combine. If they have different registration evidence and operate independently, they should stay separate. Record that decision as a negative match so the same pair is not repeatedly proposed during future imports.
Prevent the next import from recreating the problem
Map each incoming source record to the surviving CRM ID, and apply the agreed matching rules before creating a new account. Review forms, event files, enrichment uploads and system synchronisations separately. Cleaning yesterday's duplicates will not help for long if tomorrow's import creates the same accounts again.
Assign an owner to the exception queue and monitor repeated causes, not just the total number of merges. If one source keeps dropping registration IDs or splitting domains inconsistently, fix that intake. A useful first project is one segment, a written identity rule and a reviewed merge file before a full-database rollout.
Key takeaways
- Define legal entity, group and branch boundaries before you compare company records.
- Use multiple identity signals; a similar name or shared domain is not sufficient on its own.
- Protect activity history, source evidence and do-not-contact flags during every merge.
A workable review queue for ambiguous matches
Give reviewers both source records, the proposed match reasons and the conflicting fields. Ask for one of three outcomes: same entity, different entity or insufficient evidence. The final option prevents a deadline from turning uncertainty into a false merge.
Keep decisions reusable. A verified parent-child relationship or a documented non-match should inform later imports, while evidence that can change should carry a review date. That makes the queue a growing identity reference rather than a pile of disconnected one-off judgements.
What to include in a deduplication delivery
Request a survivor file, an old-to-new ID mapping, an exception file and a field-level change log. Include the identity definition and source precedence rules. These let the CRM owner check the outcome, explain it to account teams and reverse a pilot if needed.
Success is not the largest reduction in row count. It is a database where each intended account has a dependable identity, relationships remain visible and the people using it can trust its history.
Practitioner note: do not approve a merge because two names look alike; ask what proves that they represent the same business.